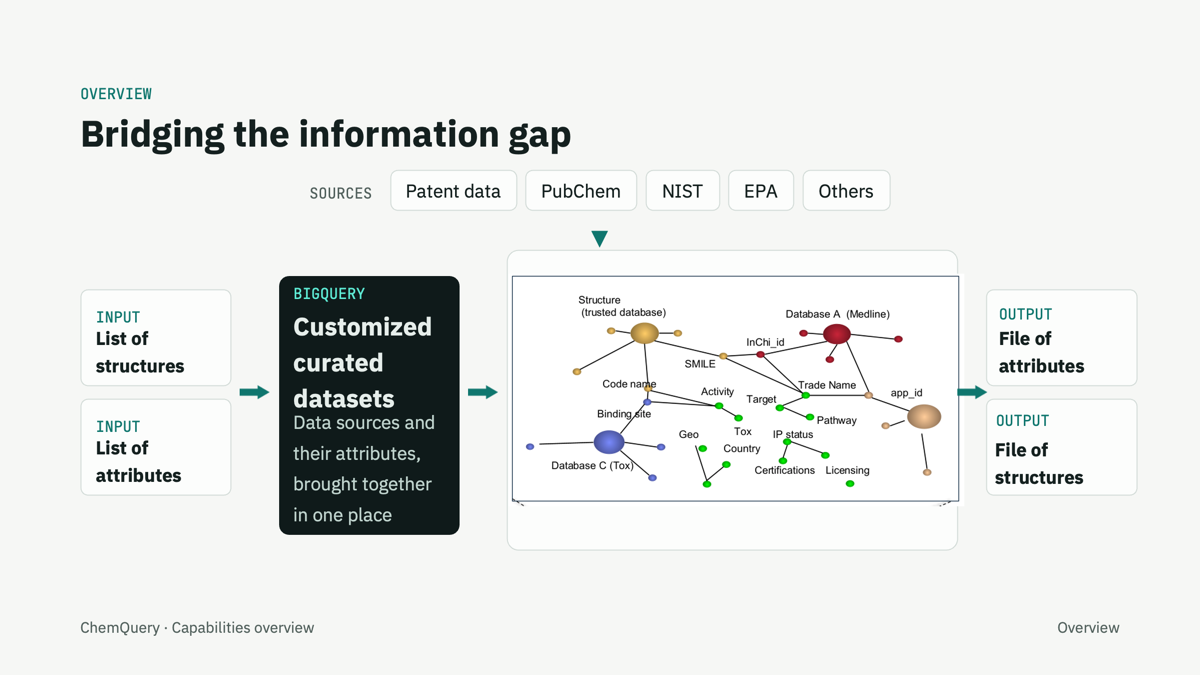
A BigQuery repository of curated data
Union table for genes & diseases
associations between diseases or conditions and gene IDs, symbols, and synonyms
Sources: OMIM, GeneCC, NIH MeSH, CTD, DOID, ICD codes, SNOMED, and others
Fields: Gene_Symbol, disease names, disease MeSH, PMIDs, source
Union table of compounds, genes & assays
associations and 167M assays linking compounds (CIDs, SMILES) to gene IDs and assay data
Sources: ChEMBL, PubChem, Pharos, TTD, DrugCentral, BindingDB, IP data, and others
Fields: GeneID, Gene_Symbol, synonyms, InChIKey, SMILES, CID; assay comment, type, value, units, source, PMIDs
Both tables sit in a BigQuery clean room; association and mapping tables connect them.
Structures in, attributes out—or the reverse.
Data from patents, PubChem, NIST, EPA, and other sources is brought together into customized, curated datasets in BigQuery. Supply a list of structures or a list of attributes; ChemQuery links the underlying sources, each with its own schema, through shared identifiers such as SMILES and InChI, and returns a file of attributes or of structures.